— Solution · Industrial biotech →
Industrial biotech
The same graph model that runs pharma research — strains, enzymes and process data as one connected record, defined by your own ontology, not ours.
- 01Strain & process R&D
- 02Scale-up
- 03Production batch record
- 04Release testing
One schema-driven platform, not a pharma product with your name stapled on
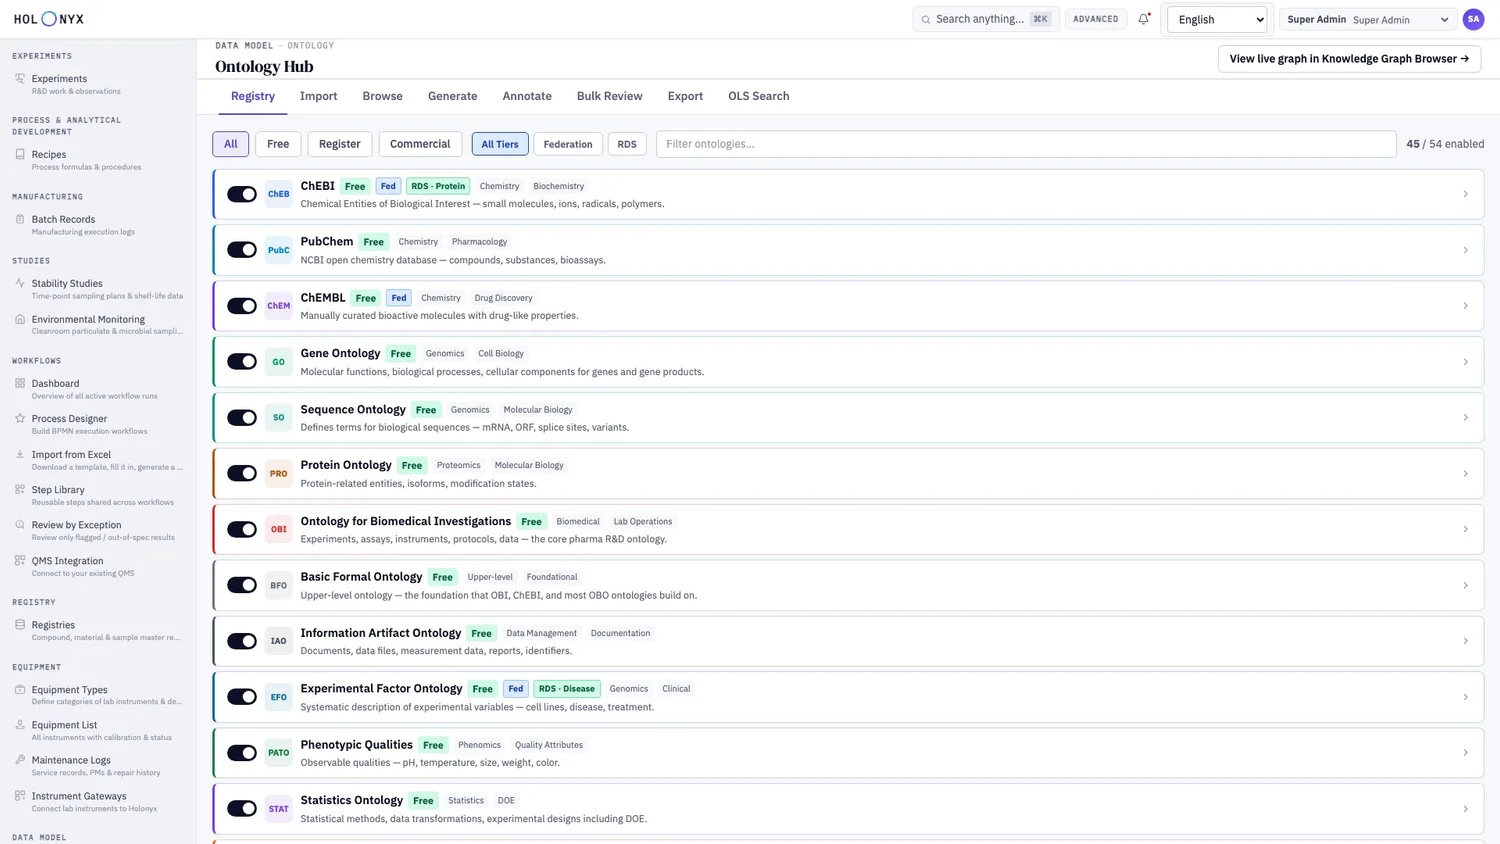
Holonyx’s data model was never written around “drug substance” or “API.” It’s built from a user-defined ontology: you tell it what kinds of things you track — strains, enzymes, feedstocks, process runs — and how they relate, and the platform builds itself around that.
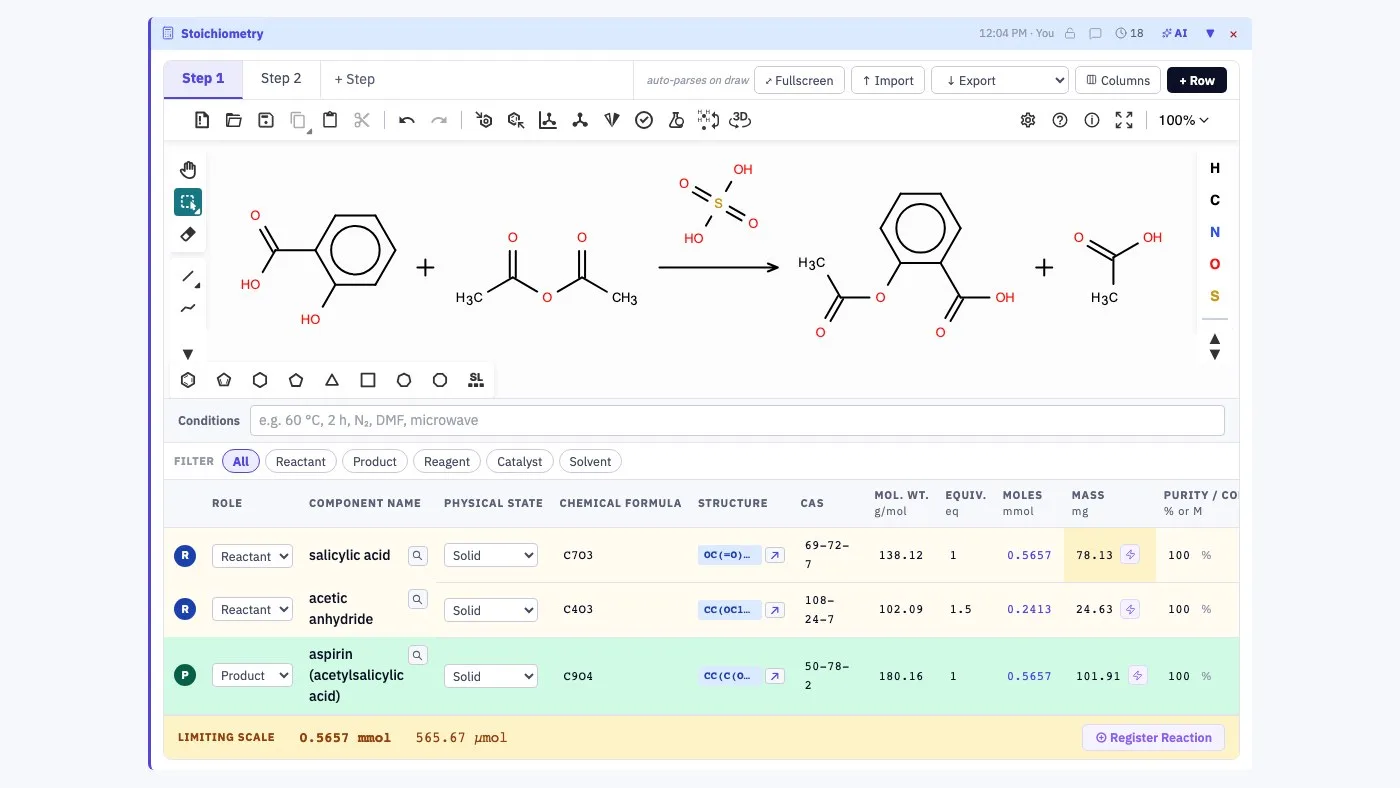
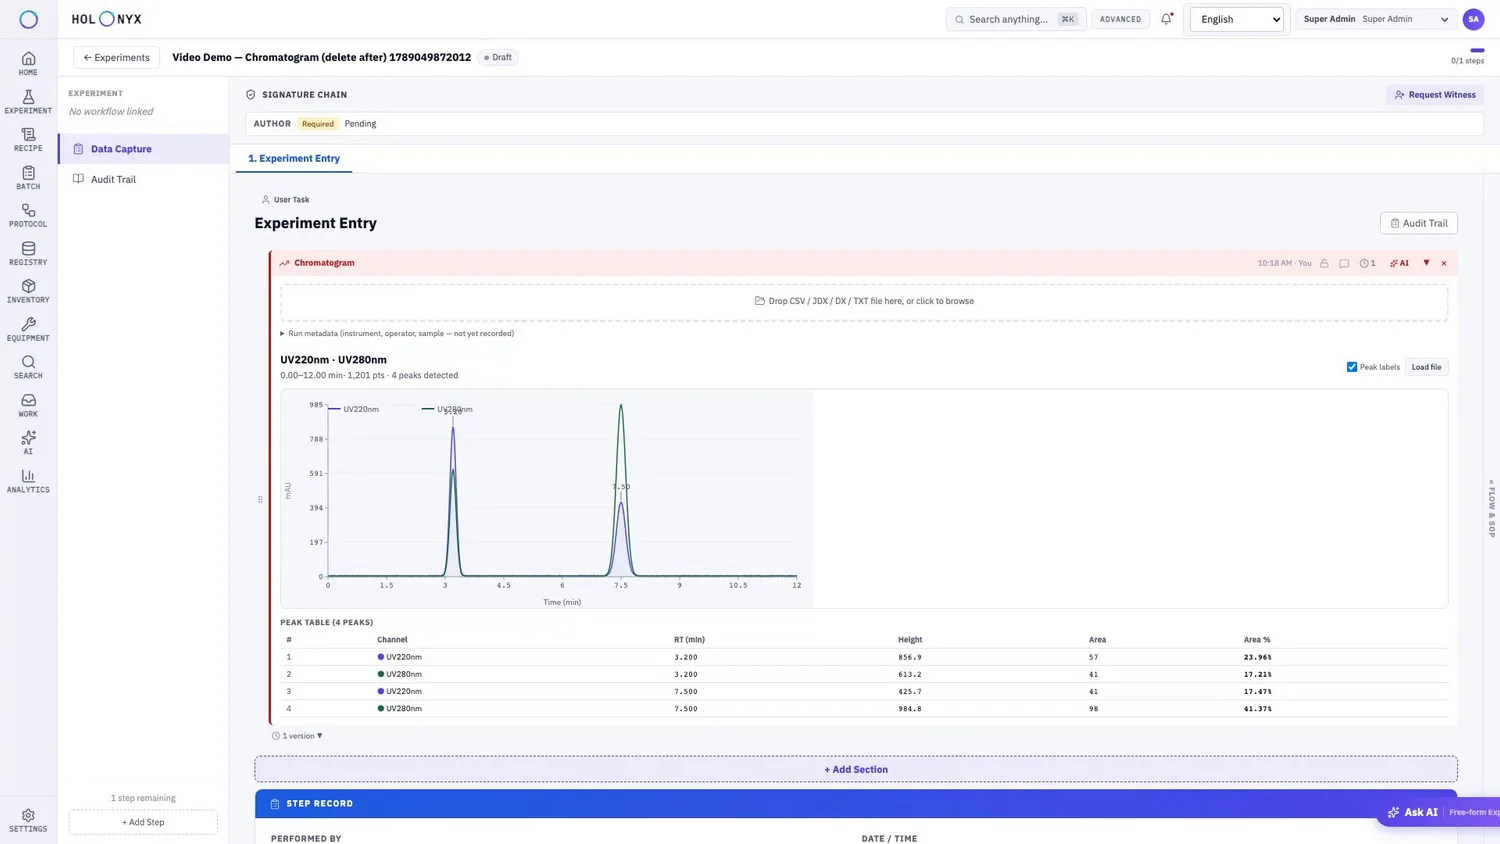
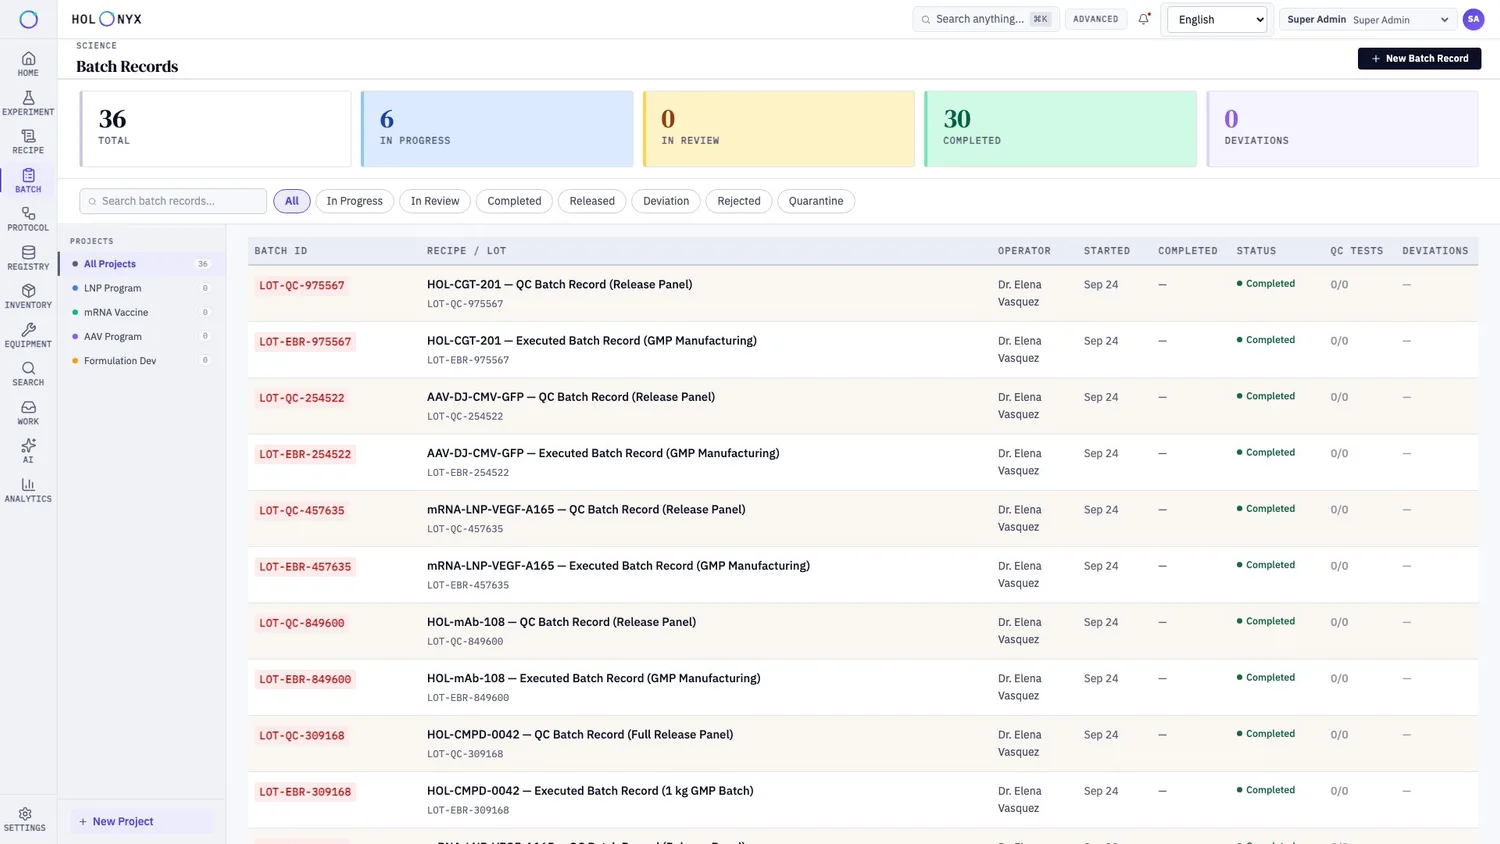
That’s why the same mechanisms that run a pharma research-to-release story apply here without being force-fit: a registry for your own materials, chemistry and stoichiometry tooling for process and formulation work, instrument gateways for whatever’s on your bench or your production floor, and a batch-record engine for the run itself.
What’s honest about this page
The chemistry, analytical, registry, and batch-record mechanisms shown here are real and already built — they’re domain-agnostic by design. What’s not claimed is a pre-built strain library, industrial-biotech-specific compliance templates, or reference workflows the way the pharma modality pages have — those would need to be built with a real customer’s process, not invented for a marketing page.
See it on the platform: Research · Lab & QC · Manufacturing · The graph model.
In the product